Teams were about to let AI confidence decide what people review
Research teams increasingly use LLMs to code qualitative data: student messages, interview transcripts, support tickets. The common workflow is simple. Accept the codes the model is confident about, and send the low-confidence ones to a person.
That only works if the confidence number means something. Classic classifiers output calibrated probabilities. LLMs write a confidence score as just another token. Before building a review pipeline on top of it, we needed to know whether that number can be trusted.
Try the finding yourself
Before the results, make the call a reviewer would make: how often is a 90%-confident model right?
Can you give me a Java example of a for-loop?
AI says: exampleconf. ≈ 0.9
Three studies, each answering the question the last one raised
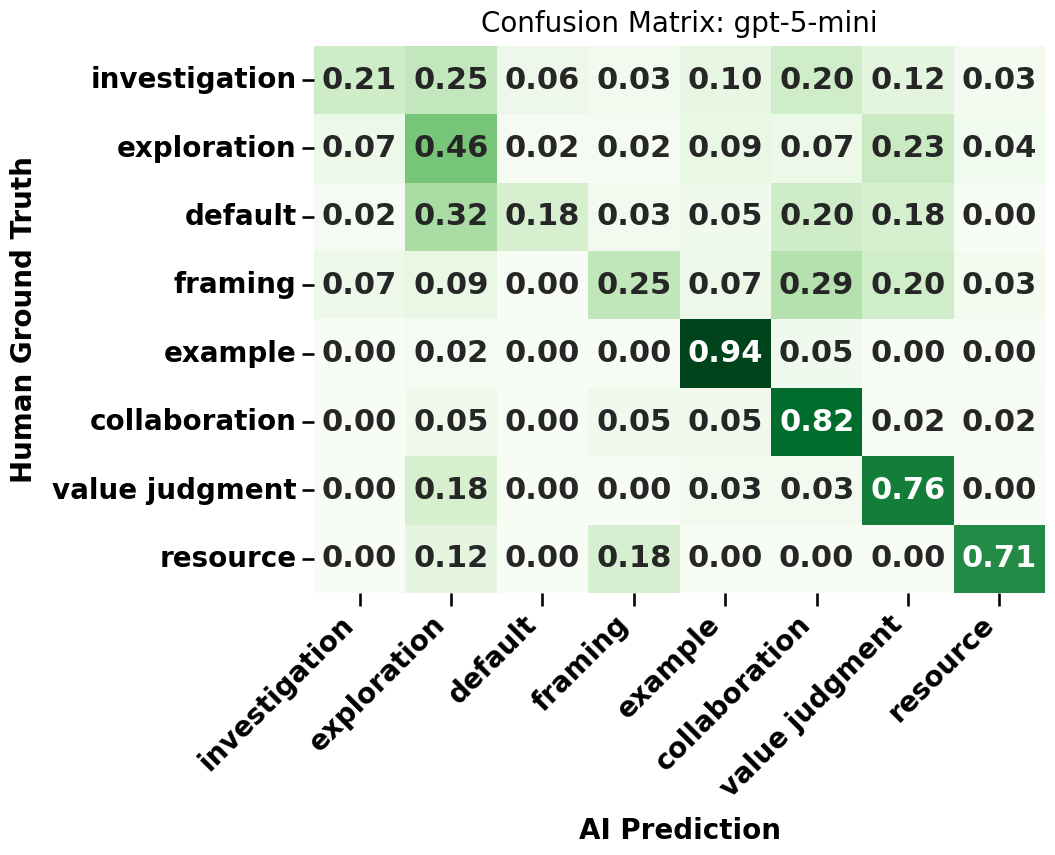
- How calibrated is it?Compared self-reported confidence with accuracy for gpt-5-mini, gemini-3-flash, and the open-weight llama-3.1-8b. ECE measures overconfidence; AUC and Spearman’s ρ measure whether higher confidence at least means more likely correct.
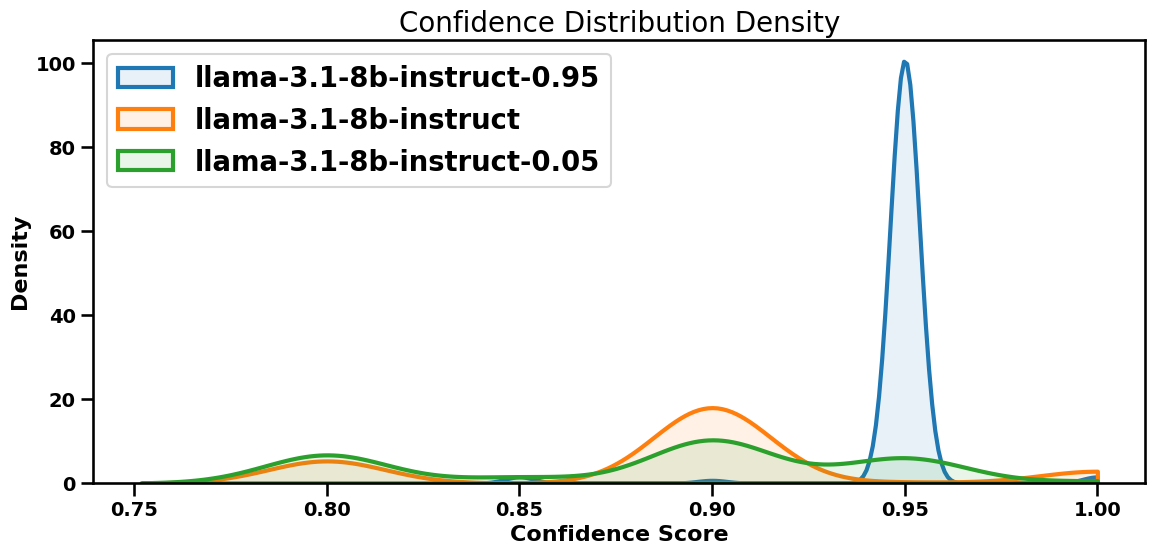
- Why can’t prompting fix it?Changed the example confidence shown in the prompt, to see whether the model could be talked into honesty.
- Can we fix it below the prompt?Used representation engineering to find a “well-calibrated” direction in the model’s activations and nudged it at inference time, evaluated on held-out data.
The data: 633 prompts students sent to ChatGPT in a graduate intro CS course, independently coded by two trained researchers into nine categories (Cohen’s κ 0.65 to 0.94). With nine overlapping categories, chance is about 11%.
Consistent overconfidence, and a habit prompts cannot move
- Accuracy is not calibrationgemini was the most accurate model, yet ranked its own correctness slightly worse than gpt-5-mini. Knowing the answer and knowing when you know it look like different abilities.
- The model only adopts plausible numbersShowing 0.95 in the prompt collapsed 96.5% of outputs to exactly 0.95. Showing 0.05 was ignored completely.
- Steering helps a littleActivation steering lifted AUC from about 0.565 to 0.585 on held-out data. A real signal exists inside the model, and the overconfidence gap stays large.
What changes for teams building human-in-the-loop AI
- Triage depends on AUC, not accuracyAround AUC 0.68, routing low-confidence items to people helps. Near 0.56 it barely beats random order. Measure discrimination on your own data first.
- Rank, don’t thresholdWith ECE above 0.40, “0.9” is not a 90% chance of being right. Use confidence to order the review queue, not to auto-accept.
- Be careful with few-shot confidenceFixed confidence values in examples can silently collapse or be ignored, changing calibration without anyone noticing.
- An option for private deploymentsFor privacy-bound, locally hosted models, activation steering gave small, consistent gains. The steering code is open source.
One dataset, one coding scheme, single-turn prompts, and Studies 2 and 3 on one open-weight model. Next I want per-category calibration, which would tell research teams which codes are safe to automate and which still need a person, plus replication on larger models and multi-turn elicitation.